数据与计算发展前沿 ›› 2026, Vol. 8 ›› Issue (4): 42-71.
CSTR: 32002.14.jfdc.CN10-1649/TP.2026.04.004
doi: 10.11871/jfdc.issn.2096-742X.2026.04.004
马乐1( ),张然2,5,韩颐堃3,于诗睿4,5,王在田2,5,宁致远2,5,张静涵6,许萍2,5,李鹏江2,5,乔子越7,琚玮8,陈冲9,王东杰10,刘鲲鹏6,汪澎洋11,王鹏飞2,5,傅衍杰12,刘春江4,5,*(),吕长天13
收稿日期:2026-01-22
出版日期:2026-08-20
发布日期:2026-08-21
通讯作者:
刘春江(E-mail: 作者简介:马乐,四川大学公共管理学院,硕士,研究方向为推荐系统、搜索澄清。
MA Le1(),ZHANG Ran2,5,HAN Yikun3,YU Shirui4,5,WANG Zaitian2,5,NING Zhiyuan2,5,ZHANG Jinghan6,XU Ping2,5,LI Pengjiang2,5,QIAO Ziyue7,JU Wei8,CHEN Chong9,WANG Dongjie10,LIU Kunpeng6,WANG Pengyang11,WANG Pengfei2,5,FU Yanjie12,LIU Chunjiang4,5,*(),LYU Changtian13
Received:2026-01-22
Online:2026-08-20
Published:2026-08-21
摘要:
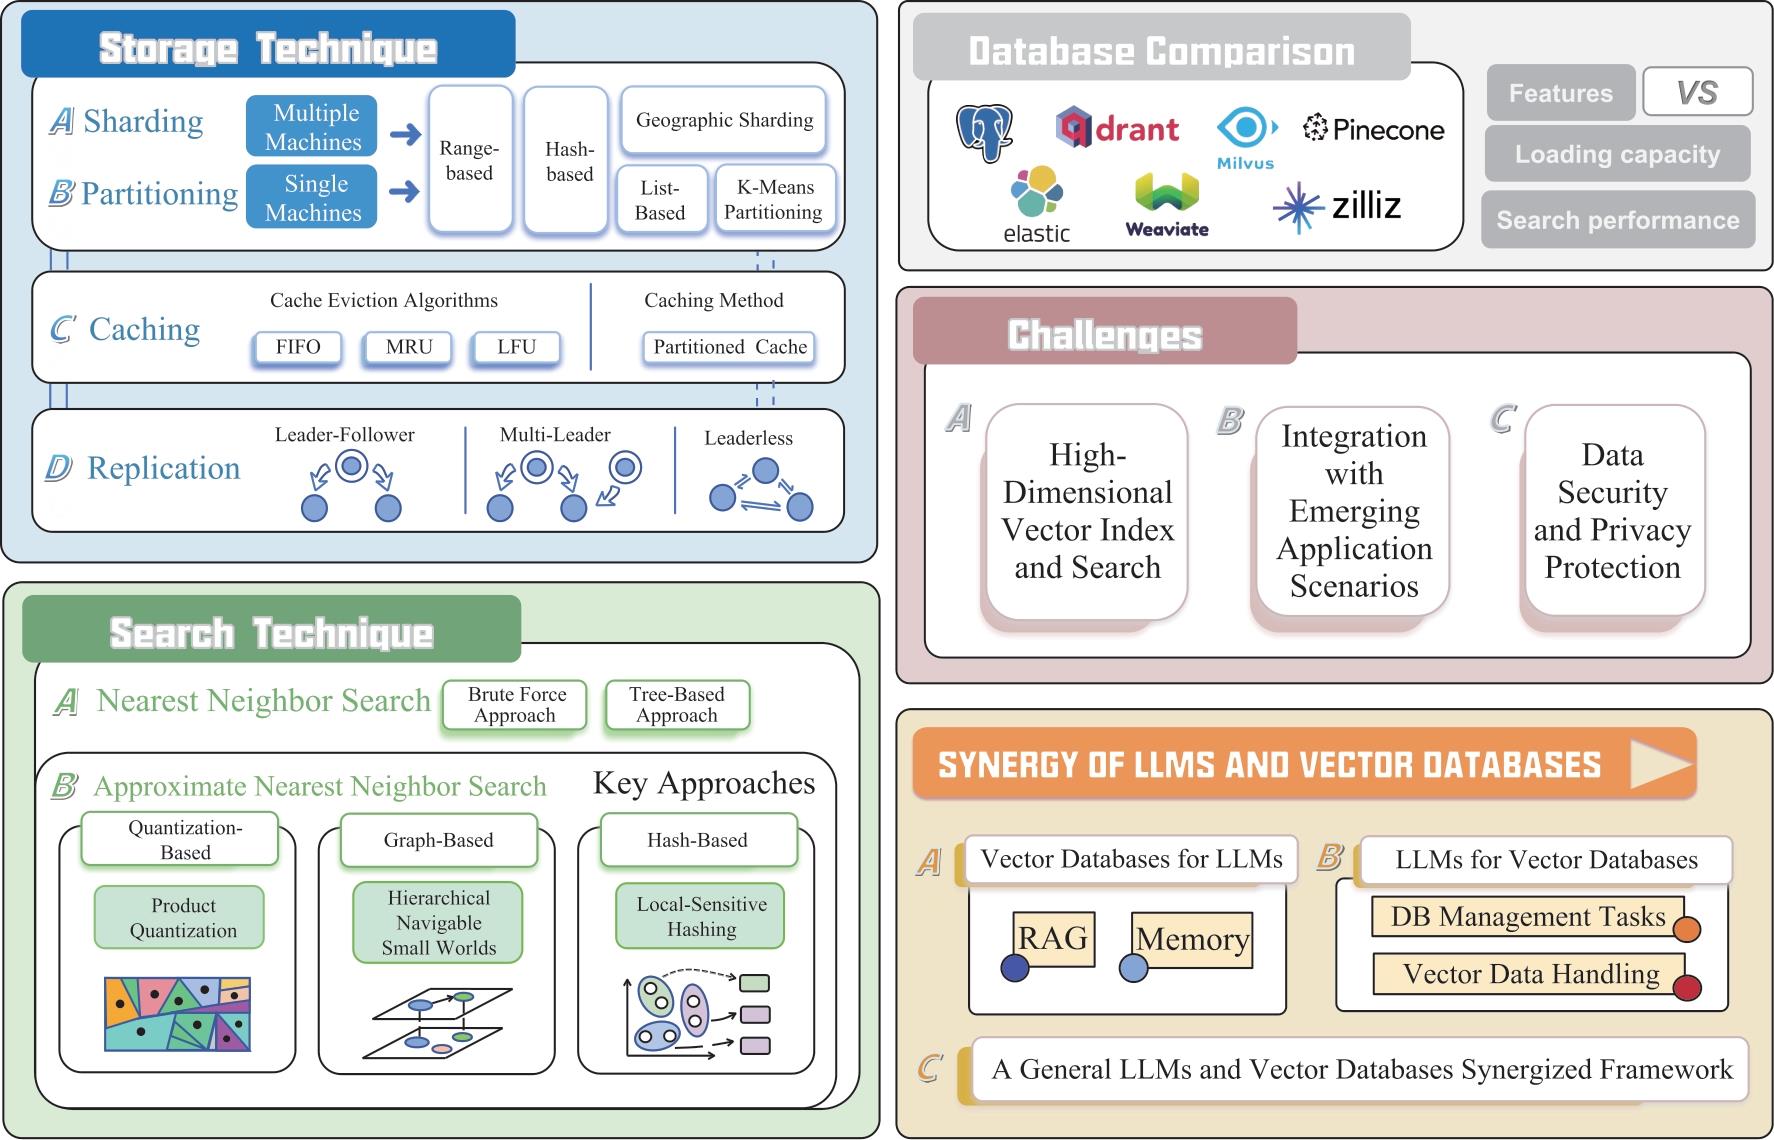
【目的】 高维向量数据的涌现已超越传统数据库的处理能力,推动向量数据库(VDBs)快速发展并与大语言模型深度融合,广泛支持现代人工智能系统。然而,现有研究多集中于近似最近邻搜索等技术细节,缺乏从系统架构层面出发的整体性综述,也未深入探讨核心技术如何协同构建VDBs的综合能力。本文旨在系统梳理向量数据库的核心设计、关键算法与架构,为其发展提供完整认知框架。【方法】 首先,围绕存储与检索两个核心维度,系统回顾VDBs的关键技术与设计理念,梳理其技术演进路径;其次,对比分析多款主流向量数据库的架构特性,总结其优势、局限和适用场景;最后,探讨向量数据库与大语言模型融合的前沿趋势,包括新型索引策略等开放问题与发展方向。【结论】 本综述可为研究人员与从业者提供系统性参考,帮助读者把握该领域技术全景与发展动态,促进向量数据库在理论与应用层面的进一步创新。
马乐, 张然, 韩颐堃, 于诗睿, 王在田, 宁致远, 张静涵, 许萍, 李鹏江, 乔子越, 琚玮, 陈冲, 王东杰, 刘鲲鹏, 汪澎洋, 王鹏飞, 傅衍杰, 刘春江, 吕长天. 向量数据库:存储与检索技术综述[J]. 数据与计算发展前沿, 2026, 8(4): 42-71.
MA Le, ZHANG Ran, HAN Yikun, YU Shirui, WANG Zaitian, NING Zhiyuan, ZHANG Jinghan, XU Ping, LI Pengjiang, QIAO Ziyue, JU Wei, CHEN Chong, WANG Dongjie, LIU Kunpeng, WANG Pengyang, WANG Pengfei, FU Yanjie, LIU Chunjiang, LYU Changtian. A Comprehensive Survey on Vector Database: Storage and Retrieval Techniques[J]. Frontiers of Data and Computing, 2026, 8(4): 42-71, https://cstr.cn/32002.14.jfdc.CN10-1649/TP.2026.04.004.
"
"
"
"
"
"
"
| Database | Query Types | Indexing Methods | NSD | Scalability | Replica tion | Sharding | Partition ing | Maximum Dimension | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| ANNS | NNS | Brute Force | Tree Based | Hash Based | Graph Based | Quantiza tion Based | Horizon tal Scaling | Vertical Scaling | ||||||||||
| PgVector | √ | √ | √ | √ | √ | √ | √ | 7 | √ | √ | √ | √ | √ | 16,000 | ||||
| QdrantCloud | √ | √ | √ | × | × | √ | √ | 4 | √ | √ | √ | √ | √ | 65,535 | ||||
| Weaviate Cloud | √ | √ | √ | × | × | √ | × | 6 | √ | × | √ | √ | √ | 65,535 | ||||
| ZillizCloud | √ | √ | √ | × | √ | √ | √ | 4 | × | √ | √ | √ | √ | 32,768 | ||||
| Milvus | √ | √ | √ | × | × | √ | √ | 6 | √ | × | √ | √ | √ | 32,768 | ||||
| ElasticCloud | √ | √ | √ | × | × | √ | × | 4 | √ | × | √ | √ | √ | N/A | ||||
| Pinecone | √ | √ | N/A | N/A | N/A | N/A | N/A | 3 | √ | √ | √ | √ | √ | N/A | ||||
"
| PgVector | QdrantCloud | WeaviateCloud | ZillizCloud | Milvus | ElasticCloud | Pinecone | |
|---|---|---|---|---|---|---|---|
| Inner Product | √ | √ | √ | √ | √ | √ | √ |
| Cosine Similarity | √ | √ | √ | √ | √ | × | √ |
| Manhattan Distance | √ | √ | √ | × | × | × | × |
| Hamming Distance | √ | × | √ | √ | √ | × | × |
| Jaccard Distance | √ | × | × | √ | √ | × | × |
| Taxicab Distance | √ | × | × | × | × | × | × |
| Euclidean Distance | √ | √ | √ | × | √ | √ | √ |
| Structural Similarity | × | × | × | × | √ | × | × |
| Maximum Inner Product | × | × | × | × | × | √ | × |
"
| PgVector | QdrantCloud | WeaviateCloud | ZillizCloud | Milvus | ElasticCloud | Pinecone | |
|---|---|---|---|---|---|---|---|
| HNSW | √ | √ | √ | √ | √ | √ | N/A |
| Flat | × | × | √ | × | √ | × | N/A |
| BINFlat | × | × | × | × | √ | × | N/A |
| IVF_Flat | × | × | × | × | √ | × | N/A |
| BIN_IVF_Flat | × | × | × | × | √ | × | N/A |
| IVF_SQ8 | × | × | × | × | √ | × | N/A |
| IVF_PQ | × | × | × | × | √ | × | N/A |
| B-tree | √ | × | × | × | × | × | N/A |
| LSH | × | × | × | √ | × | × | N/A |
| BRIN | √ | × | × | × | × | × | N/A |
| Inverted_File_Index | √ | × | × | × | √ | √ | N/A |
| SPARSE Inverted Index | × | × | × | × | × | × | N/A |
| SPARSE WAND | × | × | × | × | √ | × | N/A |
| GIST | √ | × | × | × | × | × | N/A |
| GIN | √ | × | × | × | × | × | N/A |
| DiskANN | × | √ | × | √ | × | × | N/A |
| SCANN | × | × | × | √ | × | × | N/A |
| Sparse Vector Index | × | √ | × | × | × | × | N/A |
| Parameterized index | × | √ | × | × | × | × | N/A |
"
| Case NO. | Case Type | Dataset | Dataset Size | Vector Dimensions | Filtering Rate | Test Metrics |
|---|---|---|---|---|---|---|
| 1 | Capacity | SIFT | 500K | 128 | N/A | NIV |
| 2 | Capacity | GIST | 100K | 960 | N/A | NIV |
| 3 | Search Performance | Google C4 | 500K | 1,536 | N/A | IBT, R, L, MQPS |
"
| Vector Database | Total Rank | QPS (more is better) | Recall (more is better) | Latency (less is better) | Load Duration (less is better) | 960 Dim Max Load Count (more is better) | 128 Dim Max Load Count (more is better) |
|---|---|---|---|---|---|---|---|
| Milvus | 1 | 380 | 0.982 | 12.4 | 1586 | 1000K | 9100K |
| Pinecone | 2 | 67.63 | 0.8064 | 36 | 1409 | 700K | 4100K |
| WeaviateCloud | 3 | 48.68 | 0.9957 | 123 | 2973 | 1800K | 5500K |
| Zilliz Cloud | 4 | 180.3 | 0.9942 | 6 | 3268 | 350(P) | 2000(P) |
| Qdrant Cloud | 5 | 78.72 | 0.9203 | 49.4 | 1818 | 900K | 4000K |
| PgVector | 6 | 0.8836 | 0.8528 | 2523 | 1381 | 350(P) | 2000(P) |
| Elastic Cloud | 7 | 11.29 | 0.996 | 3611 | 8671 | 350(P) | 2000(P) |
"
| [1] | CAO J, FANG J, MENG Z, et al. Knowledge graph embedding: A survey from the perspective of representation spaces[J]. ACM Computing Surveys, 2024, 56(6): 1-42. |
| [2] | POUYANFAR S, YANG Y, CHEN S C, et al. Multimedia big data analytics: A survey[J]. ACM Computing Surveys, 2018, 51(1): 1-34. |
| [3] | ZHAO W X, ZHOU K, LI J, et al. A survey of large language models[J/OL]. [2024-07-28]. https://arxiv.org/abs/2303.18223. |
| [4] | ALLAM A M, HAGGAG M H. The question answering systems: A survey[J]. International Journal of Research and Reviews in Information Sciences (IJRRIS), 2012, 2(3). |
| [5] | BIANCOFIORE G M, DELDJOO Y, NOIA T D, et al. Interactive question answering systems: Literature review[J]. ACM Computing Surveys, 2024, 56(9): 1-38. |
| [6] |
ZHANG Y, WU J, CAI J. Compact representation of high-dimensional feature vectors for large-scale image recognition and retrieval[J]. IEEE Transactions on Image Processing, 2016, 25(5): 2407-2419.
doi: 10.1109/TIP.2016.2549360 pmid: 27046897 |
| [7] | LIU Q, HU J, XIAO Y, et al. Multimodal recommender systems: A survey[J]. ACM Computing Surveys, 2024, 57(2): 1-17. |
| [8] |
ZHAO Z, FAN W, LI J, et al. Recommender systems in the era of large language models (llms)[J]. IEEE Transactions on Knowledge and Data Engineering, 2024, 36(11): 6889-6907.
doi: 10.1109/TKDE.2024.3392335 |
| [9] | TOUYA G, LOKHAT I. Deep learning for enrichment of vector spatial databases: Application to highway interchange[J]. ACM Transactions on Spatial Algorithms and Systems, 2020, 6(3): 1-21. |
| [10] | KRASKA T, BEUTEL A, CHI E H, et al. The case for learned index structures[C]// Proceedings of the 2018 international conference on management of data. 2018: 489-504. |
| [11] | WANG M, LV L, XU X, et al. An efficient and robust framework for approximate nearest neighbor search with attribute constraint[J]. Advances in Neural Information Processing Systems, 2023, 36: 15738-15751. |
| [12] | XIE X, LIU H, HOU W, et al. A brief survey of vector databases[C]// 2023 9th International Conference on Big Data and Information Analytics (BigDIA). IEEE, 2023: 364-371. |
| [13] | WANG M, XU X, YUE Q, et al. A comprehensive survey and experimental comparison of graph-based approximate nearest neighbor search[J/OL]. [2024-07-28]. https://arxiv.org/abs/2101.12631. |
| [14] | WANG Z, WANG P, PALPANAS T, et al. Graph-and Tree-based Indexes for High-dimensional Vector Similarity Search: Analyses, Comparisons, and Future Directions[J]. IEEE Data Engineering Bulletin, 2023, 46(3): 3-21. |
| [15] | JÉGOU H, DOUZE M, JOHNSON J, et al. Faiss: Similarity search and clustering of dense vectors library[J]. Astrophysics Source Code Library, 2022: ascl: 2210.024. |
| [16] | KHAN S, SINGH S, SIMHADRI H V, et al. Bang: Billion-scale approximate nearest neighbor search using a single gpu[J/OL]. [2025-11-20]. https://arxiv.org/abs/2401.11324. |
| [17] |
LI W, ZHANG Y, SUN Y, et al. Approximate nearest neighbor search on high-dimensional data—experiments, analyses, and improvement[J]. IEEE Transactions on Knowledge and Data Engineering, 2019, 32(8): 1475-1488.
doi: 10.1109/TKDE.69 |
| [18] | MOHONEY J, PACACI A, CHOWDHURY S R, et al. High-throughput vector similarity search in knowledge graphs[J]. Proceedings of the ACM on Management of Data, 2023, 1(2): 1-25. |
| [19] | PAN J J, WANG J, LI G. Vector database management techniques and systems[C]// Companion of the 2024 International Conference on Management of Data. 2024: 597-604. |
| [20] |
PAN J J, WANG J, LI G. Survey of vector database management systems[J]. The VLDB Journal, 2024, 33(5): 1591-1615.
doi: 10.1007/s00778-024-00864-x |
| [21] |
RAO T R, MITRA P, BHATT R, et al. The big data system, components, tools, and technologies: a survey[J]. Knowledge and Information Systems, 2019, 60(3): 1165-1245.
doi: 10.1007/s10115-018-1248-0 |
| [22] | WANG M, XU W, YI X, et al. Starling: An i/o-efficient disk-resident graph index framework for high-dimensional vector similarity search on data segment[J]. Proceedings of the ACM on Management of Data, 2024, 2(1): 1-27. |
| [23] | SU Y, SUN Y, ZHANG M, et al. Vexless: A serverless vector data management system using cloud functions[J]. Proceedings of the ACM on Management of Data, 2024, 2(3): 1-26. |
| [24] |
TAIPALUS T. Vector database management systems: Fundamental concepts, use-cases, and current challenges[J]. Cognitive Systems Research, 2024, 85: 101216.
doi: 10.1016/j.cogsys.2024.101216 |
| [25] | JOSHI S. Introduction to Vector Databases for Generative AI: Applications, Performance, Future Projections, and Cost Considerations[J]. International Advanced Research Journal in Science, Engineering and Technology, 2025, 12(2): 79-93. |
| [26] | ZHONG S, MO D, LUO S. Lsm-vec: A large-scale disk-based system for dynamic vector search[J/OL]. [2025-11-20]. https://arxiv.org/abs/2505.17152. |
| [27] | Oracle database using oracle sharding[EB/OL]. [2024-07-28]. https://docs.oracle.com/en/database/oracle/oracle-database/18/shard/book-index.html. |
| [28] | COSTA C H, MAIA P H M, CARLOS F. Sharding by hash partitioning[C]// Proceedings of the 17th International Conference on Enterprise Information Systems. 2015, 1: 313-320. |
| [29] | DONE P, KAMSKY A. Practical MongoDB Aggregations[M]. Packt Publishing, 2024:101-110. |
| [30] | KARGER D, LEHMAN E, LEIGHTON T, et al. Consistent hashing and random trees: Distributed caching protocols for relieving hot spots on the world wide web[C]// Proceedings of the twenty-ninth annual ACM symposium on Theory of computing. 1997: 654-663. |
| [31] |
KARGER D, SHERMAN A, BERKHEIMER A, et al. Web caching with consistent hashing[J]. Computer Networks, 1999, 31(11-16): 1203-1213.
doi: 10.1016/S1389-1286(99)00055-9 |
| [32] | MIRROKNI V, THORUP M, ZADIMOGHADDAM M. Consistent hashing with bounded loads[C]// Proceedings of the Twenty-Ninth Annual ACM-SIAM Symposium on Discrete Algorithms. Society for Industrial and Applied Mathematics, 2018: 587-604. |
| [33] | TAFT R, SHARIF I, MATEI A, et al. Cockroachdb: The resilient geo-distributed sql database[C]// Proceedings of the 2020 ACM SIGMOD international conference on management of data. 2020: 1493-1509. |
| [34] | ZHANG Y, POWER R, ZHOU S, et al. Transaction chains: achieving serializability with low latency in geo-distributed storage systems[C]// Proceedings of theACM Symposium on Operating Systems Principles. 2013: 276-291. |
| [35] | ANTONY G J, DELAVERGNE M, LEBRE A, et al. Thinking out of replication for geo-distributing applications: the sharding case[C]// 2024 IEEE 8th International Conference on Fog and Edge Computing (ICFEC). IEEE, 2024: 43-50. |
| [36] | JAFARI O., MAURYA P., NAGARKAR P., ISLAM K. M., CRUSHEV C. A survey on locality sensitive hashing algorithms and their applications[J/OL]. [2024-07-28]. https://arxiv.org/abs/2508.15290. |
| [37] | KANG D, JIANG D, YANG H, et al. Scalable Disk-Based Approximate Nearest Neighbor Search with Page-Aligned Graph[J/OL]. [2025-11-20]. https://arxiv.org/abs/2509.25487. |
| [38] | VADDI M. Hardware-Accelerated Caching for Large-Scale AI Model Training: An Intelligent Architecture for Vector Database and Model Inference Optimization[J]. Journal of Computer Science and Technology Studies, 2025, 7(12): 252-259. |
| [39] | DEWITT D, GRAY J. Parallel database systems: The future of high performance database systems[J]. Communications of the ACM, 1992, 35(6): 85-98. |
| [40] | DEWITT D J, GHANDEHARIZADEH S. Hybrid-range partitioning strategy: A new declustering strategy for multiprocessor database machine[C]// Proceedings of 16th international Conference on VLDB. 1990: 481-492. |
| [41] | HOBBS L, HILLSON S, LAWANDE S, et al. Oracle 10g data warehousing[M]. Elsevier, 2011:53-65. |
| [42] | BECK K. Test-driven development: by example[M]. Addison-Wesley Professional, 2003:32-50. |
| [43] | Weaviate[EB/OL]. [2024-07-28]. http://weaviate.io. |
| [44] | AI Search Platform[EB/OL]. [2024-07-28]. http://vespa.ai. |
| [45] | GUO R, LUAN X, XIANG L, et al. Manu: a cloud native vector database management system[J/OL]. [2024-07-28]. https://arxiv.org/abs/2206.13843. |
| [46] | GRUND D, REINEKE J. Abstract interpretation of FIFO replacement[C]// International Static Analysis Symposium. Berlin, Heidelberg: Springer Berlin Heidelberg, 2009: 120-136. |
| [47] | GRUND D, REINEKE J. Precise and efficient FIFO-replacement analysis based on static phase detection[C]// 2010 22nd Euromicro Conference on Real-Time Systems. IEEE, 2010: 155-164. |
| [48] |
MATTSON R L, GECSEI J, SLUTZ D R, et al. Evaluation techniques for storage hierarchies[J]. IBM Systems Journal, 1970, 9(2): 78-117.
doi: 10.1147/sj.92.0078 |
| [49] | GU X, DING C. On the theory and potential of LRU-MRU collaborative cache management[J]. ACM SIGPLAN Notices, 2011, 46(11): 43-54. |
| [50] | LEE D, CHOI J, KIM J H, et al. On the existence of a spectrum of policies that subsumes the least recently used (LRU) and least frequently used (LFU) policies[C]Proceedings of the 1999 ACM SIGMETRICS international conference on Measurement and modeling of computer systems. 1999: 134-143. |
| [51] |
PODLIPNIG S, BÖSZÖRMENYI L. A survey of web cache replacement strategies[J]. ACM Computing Surveys, 2003, 35(4): 374-398.
doi: 10.1145/954339.954341 |
| [52] | MITTAL S. A survey of techniques for cache partitioning in multicore processors[J]. ACM Computing Surveys, 2017, 50(2): 1-39. |
| [53] | ONGARO D, OUSTERHOUT J. In search of an understandable consensus algorithm[C]// 2014 USENIX annual technical conference (USENIX ATC 14). 2014: 305-319. |
| [54] |
GARCIA-MOLINA H, BARBARA D. How to assign votes in a distributed system[J]. Journal of the ACM (JACM), 1985, 32(4): 841-860.
doi: 10.1145/4221.4223 |
| [55] | GARMANY J, FREEMAN R G. Oracle Replication: Snapshot, Multi-master and Materialized Views Scripts[M]. Rampant TechPress, 2003:30-40. |
| [56] | BAILIS P, VENKATARAMAN S, FRANKLIN M J, et al. Quantifying eventual consistency with PBS[J]. Communications of the ACM, 2014, 57(8): 93-102. |
| [57] |
DECANDIA G, HASTORUN D, JAMPANI M, et al. Dynamo: Amazon’s highly available key-value store[J]. ACM SIGOPS Operating Systems Review, 2007, 41(6): 205-220.
doi: 10.1145/1323293.1294281 |
| [58] | FU C, WANG C, CAI D. High dimensional similarity search with satellite system graph: Efficiency, scalability, and unindexed query compatibility[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2021, 44(8): 4139-4150. |
| [59] | GAO J, LONG C. High-dimensional approximate nearest neighbor search: with reliable and efficient distance comparison operations[J]. Proceedings of the ACM on Management of Data, 2023, 1(2): 1-27. |
| [60] | MANOHAR M D, SHEN Z, BLELLOCH G, et al. Parlayann: Scalable and deterministic parallel graph-based approximate nearest neighbor search algorithms[C]// Proceedings of the 29th ACM SIGPLAN Annual Symposium on Principles and Practice of Parallel Programming. 2024: 270-285. |
| [61] | WANG Z, WANG Q, WANG P, et al. Dumpy: A compact and adaptive index for large data series collections[J]. Proceedings of the ACM on Management of Data, 2023, 1(1): 1-27. |
| [62] |
BENTLEY J L. Multidimensional binary search trees used for associative searching[J]. Communications of the ACM, 1975, 18(9): 509-517.
doi: 10.1145/361002.361007 |
| [63] | GHOJOGH B, SHARIFIAN S, MOHAMMADZADE H. Tree-based optimization: A meta-algorithm for metaheuristic optimization[J/OL]. [2024-07-28]. https://arxiv.org/abs/1809.09284. |
| [64] | DOLATSHAH M, HADIAN A, MINAEI-BIDGOLI B. Ball*-tree: Efficient spatial indexing for constrained nearest-neighbor search in metric spaces[J/OL]. [2024-07-28]. https://arxiv.org/abs/1511.00628. |
| [65] | LIU T, MOORE A W, GRAY A, et al. New algorithms for efficient high-dimensional nonparametric classification[J]. Journal of Machine Learning Research, 2006, 7(6): 56-77. |
| [66] | OMOHUNDRO S. M. Five Balltree Construction Algorithms[R]. Berkeley: International Computer Science Institute, 1989. |
| [67] | GUTTMAN A. R-trees: A dynamic index structure for spatial searching[C]// Proceedings of the 1984 ACM SIGMOD international conference on Management of data. 1984: 47-57. |
| [68] | PAOLOCIACCIA M P. M-tree: An efficient access method for similarity search in metric spaces[C]// Proceedings of the 23rd VLDB Conference, Athenes, Greece. 1997: 357-368. |
| [69] |
CAI D. A revisit of hashing algorithms for approximate nearest neighbor search[J]. IEEE Transactions on Knowledge and Data Engineering, 2019, 33(6): 2337-2348.
doi: 10.1109/TKDE.2019.2953897 |
| [70] | DATAR M, IMMORLICA N, INDYK P, et al. Locality-sensitive hashing scheme based on p-stable distributions[C]// Proceedings of the twentieth annual symposium on Computational geometry. 2004: 253-262. |
| [71] | JAFARI O, MAURYA P, NAGARKAR P, et al. A survey on locality sensitive hashing algorithms and their applications[J/OL]. [2024-07-28]. https://arxiv.org/abs/2102.08942. |
| [72] |
ABDULHAYOGLU M A, THIJS B. Use of locality sensitive hashing (LSH) algorithm to match Web of Science and Scopus[J]. Scientometrics, 2018, 116(2): 1229-1245.
doi: 10.1007/s11192-017-2569-6 |
| [73] | DIKKALA N, KAPLUN G, PANIGRAHY R. For manifold learning, deep neural networks can be locality sensitive hash functions[J/OL]. https://arxiv.org/abs/2103.06875. |
| [74] |
BOB K, TESCHNER D, KEMMER T, et al. Locality-sensitive hashing enables efficient and scalable signal classification in high-throughput mass spectrometry raw data[J]. BMC Bioinformatics, 2022, 23(1): 287.
doi: 10.1186/s12859-022-04833-5 pmid: 35858828 |
| [75] | ANDONI A, INDYK P. Near-optimal hashing algorithms for approximate nearest neighbor in high dimensions[J]. Communications of the ACM, 2008, 51(1): 117-122. |
| [76] | ANDONI A, INDYK P, et al. Beyond locality-sensitive hashing[C]// Proceedings of the twenty-fifth annual ACM-SIAM symposium on Discrete algorithms. Society for Industrial and Applied Mathematics, 2014: 1018-1028. |
| [77] | ANDONI A, RAZENSHTEYN I. Optimal data-dependent hashing for approximate near neighbors[C]// Proceedings of the forty-seventh annual ACM symposium on Theory of computing. 2015: 793-801. |
| [78] | WEISS Y, TORRALBA A, FERGUS R, et al. Spectral hashing. In advances in neural information processing systems 21[C]// Proc. of the Twenty-Second Annual Conf. on Neural Information Processing Systems, Vancouver, British Columbia, Canada. 2008: 8-11. |
| [79] | HEO J P, LEE Y, HE J, et al. Spherical hashing[C]// 2012 IEEE conference on computer vision and pattern recognition. IEEE, 2012: 2957-2964. |
| [80] | LIU H, WANG R, SHAN S, et al. Deep supervised hashing for fast image retrieval[C]// Proceedings of the IEEE conference on computer vision and pattern recognition. 2016: 2064-2072. |
| [81] | HE L, HUANG Z, YANG C, et al. A Survey on Deep Text Hashing: Efficient Semantic Text Retrieval with Binary Representation[J/OL]. [2025-11-20]. https://arxiv.org/abs/2510.27232. |
| [82] | LUO X, WANG H, WU D, et al. A survey on deep hashing methods[J]. ACM Transactions on Knowledge Discovery from Data, 2023, 17(1): 1-50. |
| [83] |
SHAN X, LIU P, WANG Y, et al. Deep hashing using proxy loss on remote sensing image retrieval[J]. Remote Sensing, 2021, 13(15): 2924.
doi: 10.3390/rs13152924 |
| [84] | Zilliz. Annoy (Approximate Nearest Neighbors Oh Yeah)[EB/OL]. [2024-07-28]. https://zilliz.com/jp/learn/what-is-annoy. |
| [85] | LIU H, DENG M, XIAO C. An improved best bin first algorithm for fast image registration[C]// Proceedings of 2011 International Conference on Electronic & Mechanical Engineering and Information Technology. IEEE, 2011, 1: 355-358. |
| [86] | BEIS J S, LOWE D G. Shape indexing using approximate nearest-neighbour search in high-dimensional spaces[C]// Proceedings of IEEE computer society conference on computer vision and pattern recognition. IEEE, 1997: 1000-1006. |
| [87] |
TAVALLALI P, TAVALLALI P, SINGHAL M. K-means tree: an optimal clustering tree for unsupervised learning[J]. Journal of Supercomputing, 2021, 77(5): 5239-5266.
doi: 10.1007/s11227-020-03436-2 |
| [88] | GUARE J. Six degrees of separation[M]// The contemporary monologue: Men., 2016: 89-93. |
| [89] | PONOMARENKO A, MALKOV Y, LOGVINOV A, et al. Approximate nearest neighbor search small world approach[C]// International Conference on Information and Communication Technologies & Applications. 2011, 17. |
| [90] |
MALKOV Y, PONOMARENKO A, LOGVINOV A, et al. Approximate nearest neighbor algorithm based on navigable small world graphs[J]. Information Systems, 2014, 45: 61-68.
doi: 10.1016/j.is.2013.10.006 |
| [91] | MALKOV Y, PONOMARENKO A, LOGVINOV A, et al. Scalable distributed algorithm for approximate nearest neighbor search problem in high dimensional general metric spaces[C]// International Conference on Similarity Search and Applications. Berlin, Heidelberg: Springer Berlin Heidelberg, 2012: 132-147. |
| [92] |
MALKOV Y A, YASHUNIN D A. Efficient and robust approximate nearest neighbor search using hierarchical navigable small world graphs[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2018, 42(4): 824-836.
doi: 10.1109/TPAMI.34 |
| [93] | XU Q, YANG J, ZHANG F, et al. Tribase: A vector data query engine for reliable and lossless pruning compression using triangle inequalities[J]. Proceedings of the ACM on Management of Data, 2025, 3(1): 1-28. |
| [94] | VAN BAALEN M, KUZMIN A, KORYAKOVSKIY I, et al. Gptvq: The blessing of dimensionality for llm quantization[J/OL]. [2025-11-20]. https://arxiv.org/abs/2402.15319. |
| [95] | LE TAN D K, LE H, HOANG T, et al. DeepVQ: A deep network architecture for vector quantization[C]// Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition Workshops. 2018: 2579-2582. |
| [96] |
WANG Y, PAN Z, LI R. A new cell-level search based non-exhaustive approximate nearest neighbor (ann) search algorithm in the framework of product quantization[J]. IEEE Access, 2019, 7: 37059-37070.
doi: 10.1109/Access.6287639 |
| [97] | XU D, Tsang I W, Zhang Y. Online product quantization[J]. IEEE Transactions on Knowledge and Data Engineering, 2018, 30(11): 2185-2198. |
| [98] | GAO J, LONG C. Rabitq: Quantizing high-dimensional vectors with a theoretical error bound for approximate nearest neighbor search[J]. Proceedings of the ACM on Management of Data, 2024, 2(3): 1-27. |
| [99] |
JEGOU H, DOUZE M, SCHMID C. Product quantization for nearest neighbor search[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2010, 33(1): 117-128.
doi: 10.1109/TPAMI.2010.57 |
| [100] |
MATSUI Y, UCHIDA Y, JÉGOU H, et al. A survey of product quantization[J]. ITE Transactions on Media Technology and Applications, 2018, 6(1): 2-10.
doi: 10.3169/mta.6.2 |
| [101] |
GE T, HE K, KE Q, et al. Optimized product quantization[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2013, 36(4): 744-755.
doi: 10.1109/TPAMI.2013.240 |
| [102] | GUO R, SUN P, LINDGREN E, et al. Accelerating large-scale inference with anisotropic vector quantization[C]// International Conference on Machine Learning. PMLR, 2020: 3887-3896. |
| [103] | XU Q, ZHANG F, LI C, et al. Harmony: A scalable distributed vector database for high-throughput approximate nearest neighbor search[J]. Proceedings of the ACM on Management of Data, 2025, 3(4): 1-28. |
| [104] | CHEN Q, ZHAO B, WANG H, et al. Spann: Highly-efficient billion-scale approximate nearest neighborhood search[J]. Advances in Neural Information Processing Systems, 2021, 34: 5199-5212. |
| [105] |
ZHAO G, XUAN K, TANIAR D, et al. Incremental k-nearest-neighbor search on road networks[J]. Journal of Interconnection Networks, 2008, 9(04): 455-470.
doi: 10.1142/S0219265908002382 |
| [106] | FARAYOLA O. A., OLORUNFEMI O. L., SHOETAN P. O. Data privacy and security in IT: A review of techniques and challenges[J]. Computer Science & IT Research Journal, 2024, 5(3): 606-615. |
| [107] |
AMAITHI RAJAN A, V V. Systematic survey: secure and privacy-preserving big data analytics in cloud[J]. Journal of Computer Information Systems, 2024, 64(1): 136-156.
doi: 10.1080/08874417.2023.2176946 |
| [108] |
ASAAD R R, ZEEBAREE S R M. Enhancing Security and Privacy in Distributed Cloud Environments: A Review of Protocols and Mechanisms[J]. Academic Journal of Nawroz University, 2024, 13(1): 476-488.
doi: 10.25007/ajnu.v13n1a2010 |
| [109] |
VALADARES D C G, PERKUSICH A, MARTINS A F, et al. Privacy-preserving blockchain technologies[J]. Sensors, 2023, 23(16): 7172.
doi: 10.3390/s23167172 |
| [110] | ACHIAM J, ADLER S, AGARWAL S, et al. Gpt-4 technical report[J/OL]. [2024-07-28]. https://arxiv.org/abs/2303.08774. |
| [111] | SHANAHAN M. Talking about large language models[J]. Communications of the ACM, 2024, 67(2): 68-79. |
| [112] | LEWIS P, PEREZ E, PIKTUS A, et al. Retrieval-augmented generation for knowledge-intensive nlp tasks[J]. Advances in neural information processing systems, 2020, 33: 9459-9474. |
| [113] | GUU K, LEE K, TUNG Z, et al. Retrieval augmented language model pre-training[C]// International conference on machine learning. PMLR, 2020: 3929-3938. |
| [114] | REGMI S, PUN C P. Gpt semantic cache: Reducing llm costs and latency via semantic embedding caching[J/OL]. [2025-11-20]. https://arxiv.org/abs/2411.05276. |
| [115] | BANG F. Gptcache: An open-source semantic cache for llm applications enabling faster answers and cost savings[C]// Proceedings of the 3rd Workshop for Natural Language Processing Open Source Software (NLP-OSS 2023). 2023: 212-218. |
| [116] | HATALIS K., CHRISTOU D., MYERS J., et al. Memory matters: The need to improve long-term memory in LLM-agents[C]// Proceedings of the AAAI Symposium Series. 2023, 2(1): 277-280. |
| [117] |
ZHOU X, SUN Z, LI G. Db-gpt: Large language model meets database[J]. Data Science and Engineering, 2024, 9(1): 102-111.
doi: 10.1007/s41019-023-00235-6 |
| [118] |
LI G, ZHOU X, ZHAO X. Llm for data management[J]. Proceedings of the VLDB Endowment, 2024, 17(12): 4213-4216.
doi: 10.14778/3685800.3685838 |
| [119] | ALBALAK A, ELAZAR Y, XIE S M, et al. 2024. A survey on data selection for language models.[J/OL]. [2025-11-20]. https://arxiv.org/abs/2402.16827. |
| [120] | CHANG S, FOSLER-LUSSIER E. How to prompt llms for text-to-sql: A study in zero-shot, single-domain, and cross-domain settings[J/OL]. [2024-07-28]. https://arxiv.org/abs/2305.11853. |
| [121] | FAN M, HAN X, FAN J, et al. Cost-effective in-context learning for entity resolution: A design space exploration[C]// 2024 IEEE 40th International Conference on Data Engineering (ICDE). IEEE, 2024: 3696-3709. |
| [122] | HUANG X, LI H, ZHANG J, et al. Llmtune: Accelerate database knob tuning with large language models[J]. CoRR, 2024. |
| [123] | TANG R, HAN X, JIANG X, et al. Does synthetic data generation of llms help clinical text mining?[J/OL]. [2024-07-28]. https://arxiv.org/abs/2303.04360. |
| [1] | 郝文玉, 刘伟, 高思远, 梁凌, 游博. 基于大模型和RAG技术的能源产业链知识问答系统设计与实现[J]. 数据与计算发展前沿, 2026, 8(4): 214-221. |
| [2] | 周晓芳, 鲍彦荣, 顾荣杰, 王昕. 基于多智能体协作和复杂网络理论的贸易事件知识图谱构建[J]. 数据与计算发展前沿, 2026, 8(4): 234-245. |
| [3] | 张梓涵,杨婉霞,赵翔,周蓓蓓,王培龙. 基于大语言模型的饮食评论知识抽取与推荐生成方法[J]. 数据与计算发展前沿, 2026, 8(3): 217-232. |
| [4] | 王丹琳, 唐云祁. 零样本语音合成技术研究进展[J]. 数据与计算发展前沿, 2026, 8(2): 204-214. |
| [5] | 王成,曾诗容,王楚文,蒋昌俊. 大语言模型驱动的市场交易行为模拟[J]. 数据与计算发展前沿, 2026, 8(1): 2-13. |
| [6] | 武智晖,黄绍晗,张逸飞,齐家兴,肖智文,曾畅,栾钟治. 基于检索增强的日志问答系统[J]. 数据与计算发展前沿, 2026, 8(1): 64-76. |
| [7] | 吴建华, 刘振宇, 曾睿, 王文瑄, 易勇, 王世轶. 基于LoRA微调大模型在网络安全等级保护测评报告质量检测中的应用研究[J]. 数据与计算发展前沿, 2025, 7(6): 111-123. |
| [8] | 董伟, 廖佳纯, 姚思诚, 陈海粟, 阚苏南. 大语言模型赋能的面向微数据脱敏的敏感信息识别分析方法[J]. 数据与计算发展前沿, 2025, 7(6): 35-43. |
| [9] | 刘典玉,刘青凯,肖雨阳,王杰. CAE-Bench: 面向结构力学仿真的大语言模型评估基准[J]. 数据与计算发展前沿, 2025, 7(4): 155-168. |
| [10] | 屈志勇,王晓光,周纯葆,史源香,乔嘉伟. 面向国产超算系统的大模型训练优化方法[J]. 数据与计算发展前沿, 2025, 7(2): 120-129. |
| [11] | 王子健, 李凯, 曹荣强, 周纯葆. 基于检查点的大模型弹性训练方法研究[J]. 数据与计算发展前沿, 2025, 7(1): 135-151. |
| [12] | 韦一金, 陈彦清, 王秀东, 樊景超. 基于大语言模型的《中国小麦品种志》信息提取[J]. 数据与计算发展前沿, 2025, 7(1): 175-185. |
| [13] | 马秋平, 张琪, 赵晓凡. 图表问答研究综述[J]. 数据与计算发展前沿, 2025, 7(1): 19-37. |
| [14] | 裴炳森,李欣,蒋章涛,刘明帅. 基于大语言模型的司法文本摘要生成与评价技术研究[J]. 数据与计算发展前沿, 2024, 6(6): 62-73. |
| [15] | 韦一金, 樊景超. 基于ChatGLM2-6B的农业政策问答系统[J]. 数据与计算发展前沿, 2024, 6(4): 116-127. |
| 阅读次数 | ||||||
|
全文 |
|
|||||
|
摘要 |
|
|||||