Frontiers of Data and Computing ›› 2026, Vol. 8 ›› Issue (4): 111-122.
CSTR: 32002.14.jfdc.CN10-1649/TP.2026.04.008
doi: 10.11871/jfdc.issn.2096-742X.2026.04.008
Previous Articles Next Articles
WANG Danlin1,2( ),TANG Yunqi2,*()
Received:2026-03-04
Online:2026-08-20
Published:2026-08-21
WANG Danlin, TANG Yunqi. Deepfake Speech Detection: Technological Evolution and Challenges[J]. Frontiers of Data and Computing, 2026, 8(4): 111-122, https://cstr.cn/32002.14.jfdc.CN10-1649/TP.2026.04.008.
Fig. 1
Evolution roadmap of audio deepfake detection techniques"
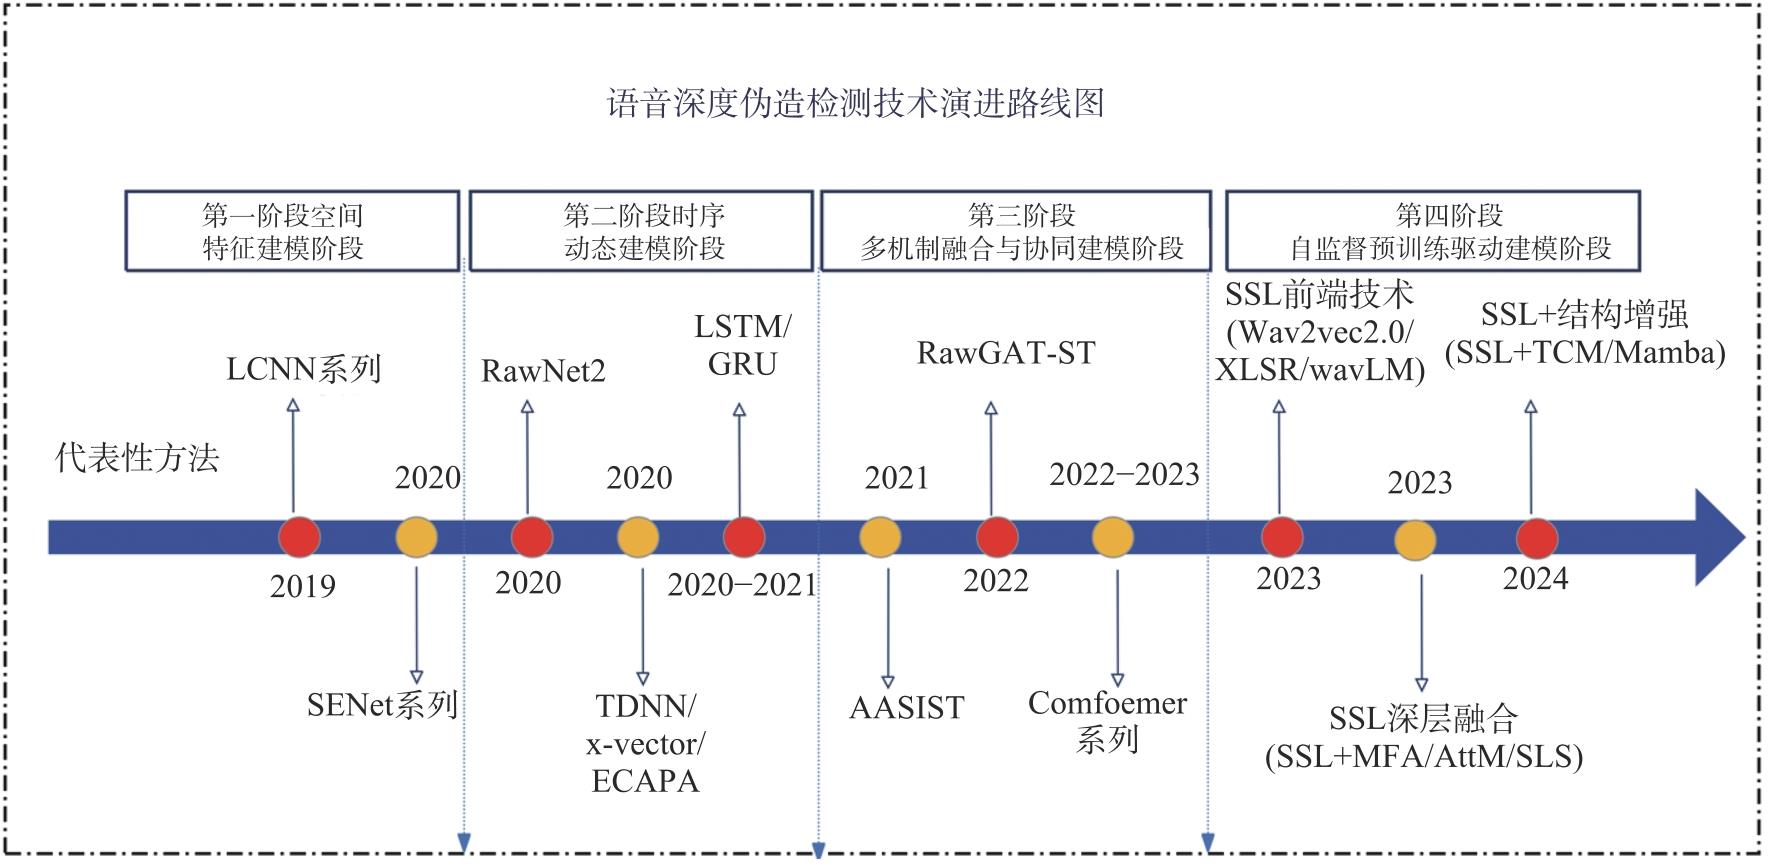
Table 1
Summary of speech deepfake detection techniques and experimental details"
| 模型 | 训练数据 | 测试数据 | 评价指标 | 实验结果 |
|---|---|---|---|---|
| STC LCNN[ | 2019LA train | 2019LA/PA eval | EER | 2019LA: 1.86%, 2019PA: 0.54% |
| GMM-ResNet[ | 2019LA train | 2021LA/DF eval | EER min t-DCF | 2021LA: EER=2.53%, min t-DCF=0.2450 2021DF: EER=15.96% |
| GMM-ResNet2[ | 2019LA train | 2021LA/DF eval | EER min t-DCF | 2019LA: EER=0.79%, min t-DCF=0.0227 2021LA: EER=2.19%, min t-DCF=0.2362 |
| SEResNet50[ | 2019LA train+dev | f2019LA eval | EER min t-DCF | EER=10.334%, min t-DCF=0.1947 |
| RW-ResNet[ | 2019LA train+dev | 2019LA eval | EER min t-DCF | EER=2.98%, mint-DCF=0.0817 |
| ECAPA-TDNN[ | VoxCeleb2 dev | VoxCeleb1/ VoxSRC2019 | EER min t-DCF | VoxCeleb1: EER=0.87%, min-DCF=0.1066 VoxSRC2019: EER=1.22% |
| RawNet2[ | 2019LA train+90% dev | 2019LA eval | EER min t-DCF | EER=5.13% min t-DCF=0.1175 |
| TranssionADD[ | ADD2023 train | ADD2023 Track2 eval | score/ accuracy | test-score=0.6249 (2nd place) |
| AASIST[ | 2019LA train | 2019LA eval | EER min t-DCF | EER=1.13%; min t-DCF=0.0347 |
| RawGAT-ST[ | 2019LA train | 2019LA eval | EER | 1.06% |
| XLS-R+SLS[ | 2019LA train | 2021LA/DF、In-the-Wild eval | EER | 2021LA: 2.87%, 2021DF: 1.92%, ITW: 7.46% |
| XLS-R+ MultiConv[ | 2019LA train | 2019/2021LA/2021DF, FoR, ITW, DFADD, LibriSeVoc, DECRO, MLAAD, ADD23-R1/R2,HABLA eval | EER | 2019LA: 0.08%, 21LA: 2.77%, 21DF: 1.43%, FoR: 5.66%, ITW: 4.44%, DFADD:6.60%, LibriSeVoc: 1.70%, DECRO (English): 13.56%, DECRO (Chinese): 1.91%, ADD23-R1: 13.87%, ADD23-R2: 21.75%, HABLA: 1.91% |
| XLSR-Conformer+ TCM[ | 2019LA train | 2021LA/DF eval | EER min t-DCF | LA EER=1.03%, min t-DCF=0.2130; DF EER=2.06%, min t-DCF=2.25 |
| HuBERT+ RawNet2[ | 2021LA FMFCC-A FAD train | 2019LA/2021LA, FMFCC-A, FAD eval | EER min t-DCF Log-loss | 2019LA: EER=1.96, min t-DCF=0.1393; 2021LA: EER=2.89%, min t-DCF=0.2182; FMFCC-A: EER=3.25, Log-loss=0.3121; FAD:EER=8.31, min t-DCF=0.1730 |
| XLSR-Mamba[ | 2019LA train | 2021LA/DF、ITW | EER | 2021LA: 0.93%, 2021DF: 1.88%, ITW: 6.71% |
| XLS-R+AASIST[ | 2019LA train | 2021LA/DF eval | EER | 2021LA: 0.82%, 2021DF: 2.85% |
| XLS-R+ AASIST2[ | 2019LA train | 2019/2021LA/ 2021DF eval | EER | 2019LA: 0.15%, 2021LA: 1.61%, 2021 DF: 2.77% |
| WavLM+AttM[ | 2019LA train | 2019/2021LA/ 2021DF eval | EER | 2019LA: 0.65%, 2021LA: 3.50%, 2021DF: 3.19% |
| WavLM+MFA[ | 2019LA train+dev | 2019/2021LA/ 2021DF eval | EER | 2019LA: 0.42%, 2021LA: 5.08%, 2021DF: 2.56% |
Table 2
Performance comparison of detection models across different development stages on multiple benchmark datasets"
| 阶段 | 模型名称 | 2019LA EER ↓/% | 2021LA EER ↓/% | 2021DF EER ↓/% | ITW EER ↓/% |
|---|---|---|---|---|---|
| 1 | LFCC-LCNN[ | 5.06 | 9.26 | 23.48 | - |
| GMM-ResNet[ | - | 2.53 | 15.96 | - | |
| 2 | ECAPA-TDNN[ | - | 5.46 | 20.33 | - |
| RawNet2[ | 0.99 | 9.5 | 22.38 | 49.00 | |
| 3 | RawGAT-ST[ | 1.06 | 10.25 | 23.26 | 52.53 |
| AASIST[ | 0.83 | 11.46 | 21.07 | 43 | |
| 4 | TCM-ADD[ | 0.18 | 2.99 | 2.14 | 7.79 |
| XLSR+SLS[ | 0.23 | 2.87 | 1.92 | 7.46 | |
| XLSR-Mamba[ | 0.42 | 0.93 | 1.88 | 6.71 | |
| XLSR+AASIST[ | 0.22 | 0.82 | 2.85 | 12.48 | |
| XLSR+AASIST2[ | 0.15 | 1.61 | 2.77 | - | |
| WavLM+MFA[ | 0.42 | 5.08 | 2.56 | - | |
| WavLM+AttM[ | 0.65 | 3.50 | 3.19 | - |
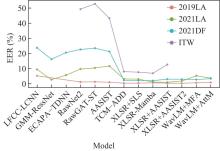
Fig. 2
Performance comparison of different models across benchmark datasets"
| [1] | 国家互联网信息办公室. 互联网信息服务深度合成管理规定[EB/OL]. (2022-12-11)[2026-04-23]. https://www.gov.cn/zhengce/zhengceku/2022-12/12/content_5731431.htm. |
| [2] | 奇安信集团. 2024人工智能安全报告[R/OL]. https://www.qianxin.com/北京:奇安信集团, 2024. |
| [3] | 新华社. “三只羊”公司使用AI伪造视频音频事件调查报道[N/OL]. 新华社, 2024. https://www.xinhuanet.com. |
| [4] | 腾讯新闻. 特朗普幕僚长深陷AI语音诈骗案: 黑客窃取其通讯录, 冒充身份接触政要并要求商人打钱[N/OL]. 腾讯新闻. [2025-05-30]. https://news.qq.com/rain/a/20250530A08QZH00. |
| [5] | 许裕雄, 李斌, 谭舜泉, 等. 语音深度伪造及其检测技术研究进展[J]. 中国图象图形学报, 2024, 29(8): 2236-2268. |
| [6] | JI Z, LI Z Y, LI P, et al. Ensemble learning for countermeasure of audio replay spoofing attack in ASVspoof 2017[C]// Interspeech 2017: Annual Conference of the International Speech Communication Association. Stockholm, Sweden: ISCA, 2017: 87-91. |
| [7] |
PHAM L, LAM P, TRAN D, et al. A comprehensive survey with critical analysis for deepfake speech detection[J]. Computer Science Review, 2025, 57: 100757.
doi: 10.1016/j.cosrev.2025.100757 |
| [8] |
KUMAR S. Real-time implementation and performance evaluation of speech classifiers in speech analysis-synthesis[J]. ETRI Journal, 2021, 43(1): 82-94.
doi: 10.4218/etrij.2019-0364 |
| [9] | WU Z, KINNUNEN T, EVANS N, et al. ASVspoof 2015: Automatic speaker verification spoofing and countermeasures challenge evaluation plan[J]. Training, 2014, 10(15): 3750. |
| [10] | WANG X, YAMAGISHI J, TODISCO M, et al. ASVspoof 2019: A large-scale public database of synthesized, converted and replayed speech[J]. Computer Speech & Language, 2020, 64: 101114. |
| [11] |
LIU X, WANG X, SAHIDULLAH M, et al. Asvspoof 2021: Towards spoofed and deepfake speech detection in the wild[J]. IEEE/ACM Transactions on Audio, Speech, and Language Processing, 2023, 31: 2507-2522.
doi: 10.1109/TASLP.2023.3285283 |
| [12] | DELGADO H, EVANS N, JUNG J, et al. ASVspoof 5 Evaluation Plan[EB/OL]. (2024-06-28)[2026-04-23]. https://www.asvspoof.org/file/ASVspoof5_Evaluation_Plan_Phase2.pdf. |
| [13] | YI J, FU R, TAO J, et al. Add 2022: the first audio deep synthesis detection challenge[C]// ICASSP 2022-2022 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP). IEEE, 2022: 9216-9220. |
| [14] | YI J, TAO J, FU R, et al. ADD 2023: The Second Audio Deepfake Detection Challenge[J]. arXiv preprint arXiv:2305.13774, 2023. |
| [15] | FRANK J, SCHÖNHERR L. Wavefake: A data set to facilitate audio deepfake detection[J]. arXiv preprint arXiv:2111.02813, 2021. |
| [16] | REIMAO R, TZERPOS V. FoR: A dataset for synthetic speech detection[C]// 2019 International Conference on Speech Technology and Human-Computer Dialogue (SpeD). IEEE, 2019: 1-10. |
| [17] |
SALVI D, HOSLER B, BESTAGINI P, et al. TIMIT-TTS: A text-to-speech dataset for multimodal synthetic media detection[J]. IEEE Access, 2023, 11: 50851-50866
doi: 10.1109/ACCESS.2023.3276480 |
| [18] | YAN Z, ZHAO Y, WANG H. VoiceWukong: Benchmarking deepfake voice detection[J]. arXiv preprint arXiv:2409.06348, 2024. |
| [19] | MÜLLER N M, CZEMPIN P, DIECKMANN F, et al. Does audio deepfake detection generalize?[J]. arXiv preprint arXiv:2203.16263, 2022. |
| [20] | DOLHANSKY B, BITTON J, PFLAUM B, et al. The deepfake detection challenge (DFDC) dataset[J]. arXiv preprint arXiv:2006.07397, 2020. |
| [21] | KWON P, YOU J, NAM G, et al. KoDF: A large-scale korean deepfake detection dataset[C]// Proceedings of the IEEE/CVF international conference on computer vision. 2021: 10744-10753. |
| [22] | KHALID H, TARIQ S, KIM M, et al. FakeAVCeleb: A novel audio-video multimodal deepfake dataset[J]. arXiv preprint arXiv:2108.05080, 2021. |
| [23] | CAI Z, STEFANOV K, DHALL A, et al. Do you really mean that?content driven audio-visual deepfake dataset and multimodal method for temporal forgery localization[C]// 2022 International Conference on Digital Image Computing: Techniques and Applications (DICTA). IEEE, 2022: 1-10. |
| [24] | CAI Z, GHOSH S, ADATIA A P, et al. AV-Deepfake1M:A large-scale LLM-driven audio-visual deepfake dataset[C]// Proceedings of the 32nd ACM International Conference on Multimedia. 2024: 7414-7423. |
| [25] |
JUNG J, WU Y, WANG X, et al. SpoofCeleb: Speech deepfake detection and SASV in the wild[J]. IEEE Open Journal of Signal Processing, 2025, 6: 68-77.
doi: 10.1109/OJSP.2025.3529377 |
| [26] | HUANG W, GU Y, WANG Z, et al. SpeechFake: A large-scale multilingual speech deepfake dataset toward cutting-edge speech generation methods[C]// ACL 2025: 63rd Annual Meeting of the Association for Computational Linguistics. Vienna, Austria: Association for Computational Linguistics, 2025: 9985-9998. |
| [27] | LI X F, LI K, ZHENG Y F, et al. Safeear: Content privacy-preserving audio deepfake detection[C]// CCS 2024: ACM SIGSAC Conference on Computer and Communications Security. Salt Lake City, UT, USA: ACM, 2024: 3585-3599. |
| [28] |
MA H, YI J, WANG C, et al. CFAD: A Chinese dataset for fake audio detection[J]. Speech Communication, 2024, 164: 103122.
doi: 10.1016/j.specom.2024.103122 |
| [29] | HOANG V, PHAM V T, XUAN H N, et al. VSASV: A Vietnamese dataset for spoofing-aware speaker verification[C]// Interspeech 2024:Annual Conference of the International Speech Communication Association. Kos, Greece: ISCA, 2024: 4288-4292. |
| [30] | LAVRENTYEVA G, NOVOSELOV S, Tseren A, et al. STC antispoofing systems for the ASVspoof2019 challenge[J]. arXiv preprint arXiv:1904.05576, 2019. |
| [31] | LEI Z, WEN Y, YANG Y, et al. Group GMM-ResNet for Detection of Synthetic Speech Attacks[C]// Proc. Interspeech 2023. 2023: 3187-3191. |
| [32] | LEI Z, YAN H, LIU C, et al. GMM-ResNet2:Ensemble of Group ResNet Networks for Synthetic Speech Detection[C]// ICASSP 2024-2024 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP). 2024: 12101-12105. |
| [33] | MALTBY H, WALL J, GLACKIN C, et al. A frequency bin analysis of distinctive ranges between human and deepfake generated voices[C]// IJCNN 2024: International Joint Conference on Neural Networks. Yokohama, Japan: IEEE, 2024: 1-7. |
| [34] | TAK H, JUNG J, PATINO J, et al. End-to-end spectro-temporal graph attention networks for speaker verification anti-spoofing and speech deepfake detection[J]. arXiv preprint arXiv:2107.12710, 2021. |
| [35] | DESPLANQUES B, THIENPONDT J, DEMUYNCK K. ECAPA-TDNN: Emphasized channel attention, propagation and aggregation in TDNN based speaker verification[J]. arXiv preprint arXiv:2005.07143, 2020. |
| [36] | TAK H, PATINO J, TODISCO M, et al. End-to-end anti-spoofing with RawNet2[C]// ICASSP 2021-2021 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP). IEEE, 2021: 6369-6373. |
| [37] | LIU J, SU Z, HUANG H, et al. TranssionADD: A multi-frame reinforcement based sequence tagging model for audio deepfake detection[J]. arXiv preprint arXiv:2306.15212, 2023. |
| [38] | JUNG J W, HEO H S, TAK H, et al. AASIST: Audio anti-spoofing using integrated spectro-temporal graph attention networks[C]//ICASSP 2022: IEEE International Conference on Acoustics, Speech and Signal Processing.Singapore:IEEE, 2022: 6367-6371. |
| [39] | ZHANG Q, WEN S, HU T. Audio deepfake detection with self-supervised XLS-R and SLS classifier[C]// Proceedings of the 32nd ACM International Conference on Multimedia. 2024: 6765-6773. |
| [40] | TRAN H M, LOLIVE D, SINI A, et al. Multi-level SSL Feature Gating for Audio Deepfake Detection[C]// Proceedings of the 33rd ACM International Conference on Multimedia. 2025: 11766-11775. |
| [41] | TRUONG D T, TAO R, NGUYEN T, et al. Temporal-channel modeling in multi-head self-attention for synthetic speech detection[J]. arXiv preprint arXiv:2406. 17376, 2024. |
| [42] |
LI L, LU T, MA X, et al. Voice deepfake detection using the self-supervised pre-training model hubert[J]. Applied Sciences, 2023, 13(14): 8488.
doi: 10.3390/app13148488 |
| [43] |
XIAO Y, DAS R K. XLSR-Mamba: A dual-column bidirectional state space model for spoofing attack detection[J]. IEEE Signal Processing Letters, 2025, 32: 1276-1280.
doi: 10.1109/LSP.2025.3547861 |
| [44] | ZHANG Y, LU J, SHANG Z, et al. Improving short utterance anti-spoofing with aasist2[C]// ICASSP 2024-2024 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP). IEEE, 2024: 11636-11640. |
| [45] | GUO Y, HUANG H, CHEN X, et al. Audio deepfake detection with self-supervised wavlm and multi-fusion attentive classifier[C]// ICASSP 2024-2024 IEEE International Conference on Acoustics,Speech and Signal Processing(ICASSP).IEEE, 2024: 12702-12706. |
| [46] | DOWERAH S, KULKARNI A, KULKARNI A, et al. Speech df arena: A leaderboard for speech deepfake detection models[J]. arXiv preprint arXiv:2509. 02859, 2025. |
| [47] | WANG X, YAMAGISHI J. A comparative study on recent neural spoofing countermeasures for synthetic speech detection[J]. arXiv preprint arXiv:2103.11326, 2021. |
| [48] |
ZHANG Y, JIANG F, DUAN Z. One-class learning towards synthetic voice spoofing detection[J]. IEEE Signal Processing Letters, 2021, 28: 937-941.
doi: 10.1109/LSP.2021.3076358 |
| [49] | REDDY T U K, VARUN S C, SREEKANTH K P K S, et al. Evince the artifacts of spoof speech by blending vocal tract and voice source features[J]. arXiv preprint arXiv:2212.02013, 2022. |
| [50] | CUCCOVILLO L, GERHARDT M, AICHROTH P. Audio spectrogram transformer for synthetic speech detection via speech formant analysis[C]// WIFS 2023: IEEE International Workshop on Information Forensics and Security. Nürnberg, Germany: IEEE, 2023: 1-6. |
| [51] | SHIN H, HEO J, KIM J, et al. Hm-conformer: A conformer-based audio deepfake detection system with hierarchical pooling and multi-level classification token aggregation methods[C]// ICASSP 2024-2024 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP). IEEE, 2024: 10581-10585. |
| [52] | TAK H, KAMBLE M, PATINO J, et al. RawBoost: A raw data boosting and augmentation method applied to automatic speaker verification anti-spoofing[C]// ICASSP 2022: IEEE International Conference on Acoustics, Speech and Signal Processing. Singapore: IEEE, 2022: 6382-6386. |
| [53] | PAN Z, LIU T, SAILOR H B, et al. Attentive merging of hidden embeddings from pre-trained speech model for anti-spoofing detection[J]. arXiv preprint arXiv:2406.10283, 2024. |
| [1] | WANG Mengle, WU Xinqian, CHEN Zugang, LI Jing, LI Guoqing. Development and Application of a Quality Evaluation Model for In Situ Datasets [J]. Frontiers of Data and Computing, 2026, 8(4): 99-110. |
| [2] | YUAN Huifeng,ZHU Yujing,PAN Yuying,ZHANG Rongwang,JIN Zhong. A High-Quality Ocean Observation Profile Datasets Construction Scheme Based on Multi-Source Data Cleaning and Fusion [J]. Frontiers of Data and Computing, 2026, 8(3): 68-80. |
| [3] | ZHOU Yuming, ZHANG Yiming, LIU Yuanyuan, HUANG Shan. A Review of the Research on Remote Sensing Satellite Image Ship Detection Sample Dataset [J]. Frontiers of Data and Computing, 2026, 8(2): 215-226. |
| [4] | WU Zhaochen, LU Changfa, LI Gang, LAN Chenyang, WANG Cifeng. Research on Construction of a Semantic Association-Driven Space Science Data Repository System and Dataset Association Recommendation [J]. Frontiers of Data and Computing, 2025, 7(4): 67-78. |
| Viewed | ||||||
|
Full text |
|
|||||
|
Abstract |
|
|||||